Cost calculation
How Passcard calculates costs
Reproduce token costs with illustrative rates and a recorded Codex session.
Illustrative counts and rates, frozen on 14 September 2026; calculated with the product’s tokensCost function.
Recorded Codex CLI 0.154.0 usage on macOS uses a frozen fallback price, not a verified provider rate.
What Passcard calculates
Cost = recorded tokens × model API prices, summed across events.
This teaching example is frozen on 14 September 2026: not a captured customer session or a current provider price quote. Totals use Passcard’s shared tokensCost function.
1. Separate overlapping counts
12,000 input tokens include 10,000 cached tokens, leaving 2,000 uncached. The 1,000 output tokens already include 400 reasoning tokens. Neither subset is added again. Cache writes are zero.
2. Apply the rates
Using fixed, illustrative rates:
| Category | Tokens | USD / million | USD |
|---|---|---|---|
| Uncached input | 2,000 | $3.00 | $0.006 |
| Cached input | 10,000 | $0.30 | $0.003 |
| Output (includes reasoning) | 1,000 | $15.00 | $0.015 |
| Cost | $0.024 | ||
$0.006 + $0.003 + $0.015 = $0.024. Sum unrounded amounts; round the final display.
3. Add cache writes, if present
For 4,000 Claude-style cache writes including 1,000 one-hour writes, price 3,000 at the five-minute rate and 1,000 at the one-hour rate.
At assumed rates of $3.75 and $6 per million: $0.024 + $0.01125 + $0.006 = $0.04125. The one-hour count is bounded by total writes; if its rate is missing and writes are priced, Passcard uses twice the input rate.
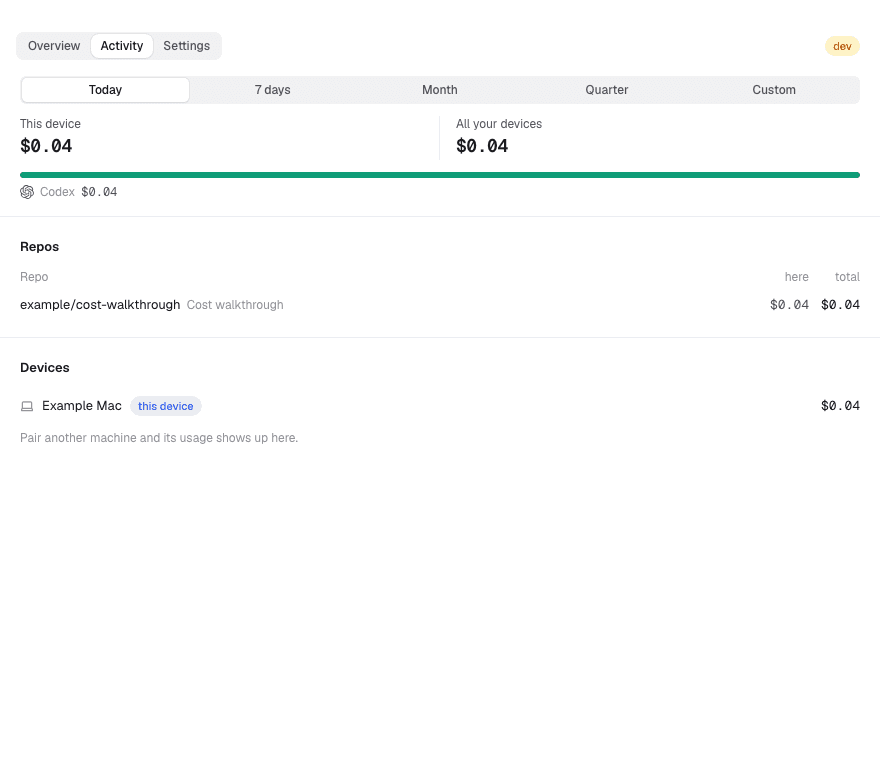
Recorded example: $0.039332
On 14 September 2026, Codex CLI 0.154.0 on macOS reported gpt-6-astra: 18,520 input tokens, including 11,904 cached, plus 10 output tokens. The task returned a fixed marker without tools or file reads. Input includes CLI context; reasoning and cache writes were zero.
Passcard bundled offline snapshot: the gpt-6 family falls back to gpt-5.6 rates. Frozen input $5, cached input $0.50 and output $30 per million tokens. These are fallback assumptions, not a verified gpt-6-astra price or provider invoice. Snapshot: .
| Category | Tokens | USD / million | USD |
|---|---|---|---|
| Uncached input | 6,616 | $5.00 | $0.033080 |
| Cached input | 11,904 | $0.50 | $0.005952 |
| Output | 10 | $30.00 | $0.000300 |
| Estimate at frozen fallback rates | $0.039332 | ||
$0.033080 + $0.005952 + $0.000300 = $0.039332. Download the counters, rates and result (JSON); identifiers, paths, prompts and responses were omitted.
Check your own session
Follow the Claude Code or Codex setup guide. Match workspace, person, agent, device and dates. Record the model, normalized counts, rate date and any fallback rates. Calculate each event before summing: models or rates can change during a session.
The price ledger preserves effective dates. Hourly updates need agreement from two feeds; unknown models may use flagged fallback rates. These examples stay frozen.
Why bills differ
Subscriptions, credits, discounts and billing rules affect actual charges. Missing or unsupported local logs and estimated token counts affect coverage. Cloud-only work is outside this collection path. Reconcile charges with your provider’s billing records.